
Split survey data into lines#
We will try and automatically split a survey into flight lines using various techniques and compare there results to the hand-split lines from the published survey data.
[1]:
%load_ext autoreload
%autoreload 2
import numpy as np
import pandas as pd
import plotly.io as pio
import airbornegeo
pio.renderers.default = "notebook"
Load data#
This is a subset of the BAS AGAP survey over Antarctica’s Gamburtsev Subglacial Mountains. The file is downloaded and subset in the notebook AGAP_magnetic_survey.
[2]:
data_df = pd.read_csv("data/AGAP_magnetic_survey_processed_blocked.csv")
# only keep relevant columns
data_df = data_df[
[
"easting",
"northing",
"latitude",
"longitude",
"unixtime",
"line",
]
]
# retain only a subset of lines
data_df = data_df[(data_df.line.between(168, 176)) | (data_df.line.between(90, 127))]
# Construct Survey without line_column set initially
# The CSV has a "line" column that we'll process below
survey = airbornegeo.Survey(
data_df,
latitude_column="latitude",
longitude_column="longitude",
copy=False,
)
# rename lines starting from 1 using the functional API
survey.data["original_line"] = airbornegeo.unique_line_id(survey.data, "line")
survey.data = survey.data.drop(columns="line")
# Now bind line_column to the created original_line column
survey.line_column = "original_line"
# sort by time and line
# survey.data = survey.data.sort_values(by=["original_line", "unixtime"])
survey.data = survey.data.sort_values(by=["unixtime"])
survey.data.head()
[2]:
| easting | northing | latitude | longitude | unixtime | original_line | |
|---|---|---|---|---|---|---|
| 296434 | 1.307592e+06 | 550872.871854 | -76.994863 | 67.154886 | 1.229692e+09 | 39 |
| 296435 | 1.307687e+06 | 550688.969771 | -76.994719 | 67.163218 | 1.229692e+09 | 39 |
| 296436 | 1.307759e+06 | 550494.204796 | -76.994795 | 67.171604 | 1.229692e+09 | 39 |
| 296437 | 1.307808e+06 | 550291.472678 | -76.995097 | 67.179919 | 1.229692e+09 | 39 |
| 296438 | 1.307832e+06 | 550082.907535 | -76.995633 | 67.188056 | 1.229692e+09 | 39 |
[3]:
print(f"Originally {len(survey.data.original_line.unique())} lines")
Originally 47 lines
[4]:
survey.plotly_points(
color_col="original_line",
hover_cols=[
"unixtime",
],
robust=False,
size=3,
)
Split lines on time gaps#
Here we assume any time gap greater than 2 minutes between successive points marks the end of one line and the start of another.
[5]:
survey.split_into_segments(
threshold=60 * 2, # 2 minutes
column_name="unixtime",
result_column="segments_by_time",
)
print(f"{len(survey.data.segments_by_time.unique())} segments")
46 segments
[6]:
survey.data["time_dif"] = survey.data.groupby("segments_by_time").unixtime.diff()
print(f"Average jump between points: {np.mean(survey.data['time_dif']):.2f} seconds")
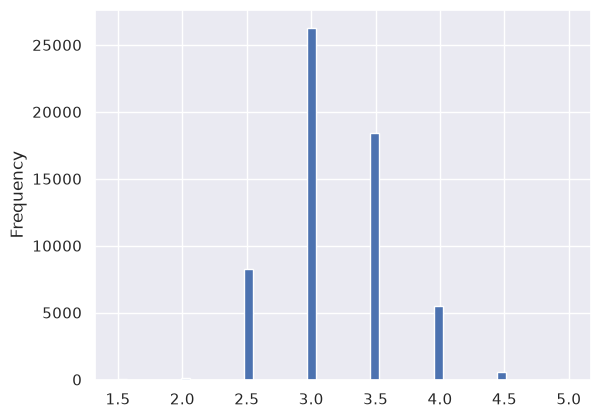
survey.data.time_dif.plot.hist(bins=50)
survey.data["time_dif"].describe()
Average jump between points: 3.19 seconds
[6]:
count 59162.000000
mean 3.192598
std 0.440530
min 1.500000
25% 3.000000
50% 3.000000
75% 3.500000
max 5.000000
Name: time_dif, dtype: float64
[7]:
survey.plotly_points(
color_col="segments_by_time",
hover_cols=[
"original_line",
"unixtime",
],
robust=False,
size=3,
)
Split lines on distance gaps#
Here we assume any distance gap greater than 5 km between successive points marks the end of one line and the start of another.
[8]:
survey.relative_distance()
survey.split_into_segments(
threshold=5e3, # 5 km
column_name="relative_distance",
result_column="segments_by_distance",
)
print(f"{len(survey.data.segments_by_distance.unique())} segments")
1 segments
[9]:
survey.plotly_points(
color_col="segments_by_distance",
hover_cols=["original_line", "relative_distance"],
robust=False,
size=3,
)
Split lines on track / heading changes#
Here we assume any change of track (heading) more than 45 degrees between successive points marks the end of one line and the start of another. First we need to calculate the track from the latitude and longitude of the data.
Note that split_into_segments compares one point’s difference against the threshold. That suits a survey where the turn happens between two samples, but on densely sampled data a turn is spread over hundreds of points, and each individual step is smaller than the navigation noise. For those surveys use split_at_turns, shown below, which measures the turn rate over a distance instead. Note also that the test is one-sided unless absolute=True is passed, so by default only right
turns (increasing track) split the data.
[10]:
survey.track()
survey.plotly_points(
color_col="track",
hover_cols=["original_line"],
size=3,
)
[11]:
survey.data = survey.data.sort_values("unixtime")
survey.split_into_segments(
threshold=40, # 20 degree track change
column_name="track",
angular_difference=True, # the difference between two values on either side of (0/360) should be small
result_column="segments_by_track",
)
print(f"{len(survey.data.segments_by_track.unique())} segments")
22 segments
[12]:
survey.plotly_points(
color_col="segments_by_track",
hover_cols=["original_line", "track"],
robust=False,
size=3,
)
Split lines at turns#
The methods above all look for a gap: a jump in time, in distance, or in track between two successive points. Turning is different, because it is a condition sustained over many points. On this survey a 180 degree turn is flown over tens of kilometres, so no single pair of points shows a large track change, and the per-point noise in track is bigger than the turn itself.
turn_rate handles this by smoothing the track over a distance before differentiating it, and returning degrees per kilometre. Because the window is a distance and not a number of points, the same threshold means the same thing whatever the sampling rate. The smoothing is circular, so a track wandering either side of north does not average to south.
[13]:
# the turn rate is measured per kilometre along the track, so the
# survey needs a cumulative distance column first
survey.along_track_distance("distance_along_line")
survey.turn_rate()
# straight survey flight sits well below 0.5 deg/km; a turn is an
# order of magnitude above it
print(survey.data.turn_rate.describe())
survey.plotly_points(
color_col="turn_rate",
hover_cols=["original_line", "track"],
size=3,
)
count 59208.000000
mean 0.129088
std 0.082327
min 0.023480
25% 0.084263
50% 0.112328
75% 0.151301
max 1.534107
Name: turn_rate, dtype: float64
split_at_turns thresholds that rate and starts a new line wherever the aircraft starts, or stops, turning.
By default each turn becomes a line of its own, so an out-and-back flight gives three lines: the outward leg, the turn, and the return leg. Pass keep_turns=False to keep only the straight runs and leave the turns unnamed, and min_length to drop runs shorter than a given distance.
[14]:
survey.split_at_turns(
max_turn_rate=0.5, # degrees per km
result_column="segments_by_turns",
)
# the new names extend the ones they came from, e.g. line 3 becomes
# "3", "3_1", "3_2"; renumber them for plotting
print(sorted(survey.data.segments_by_turns.unique())[:6])
survey.data["segments_by_turns"] = airbornegeo.unique_line_id(
survey.data, "segments_by_turns"
)
print(f"{survey.data.segments_by_turns.nunique()} lines")
['1.0', '1.1', '10.0', '11.0', '12.0', '13.0']
63 lines
[15]:
survey.plotly_points(
color_col="segments_by_turns",
hover_cols=["original_line", "turn_rate"],
robust=False,
size=3,
)
Keeping only the straight runs instead, which is usually what you want if the lines are going to be filtered or levelled along their length:
[16]:
survey.split_at_turns(
max_turn_rate=0.5,
min_length=10e3, # drop straight runs shorter than 10 km
keep_turns=False,
result_column="straight_runs",
)
kept = survey.data.straight_runs.notna()
print(f"{survey.data.straight_runs.nunique()} lines, {kept.mean():.1%} of points kept")
# compare with the published lines this survey was released with
print(f"{survey.data.original_line.nunique()} lines as published")
48 lines, 99.2% of points kept
47 lines as published